
Loading...
Searching...
No Matches
opennn::LSTMOperator Struct Reference
#include <opennn/network/layers/lstm_layer.h>
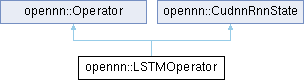
Inheritance diagram for opennn::LSTMOperator:
Public Types | |
| enum | ForwardSlot { InputSlot = 0 , ForgetGateSlot , InputGateSlot , CandidateGateSlot , OutputGateSlot , CellStateSlot , HiddenStateSlot , CellActivationSlot , CudnnInputSequenceSlot , CudnnOutputSequenceSlot , OutputSlot } |
| enum | BackwardSlot { OutputDeltaSlot = 0 , InputDeltaSlot , HiddenDeltaScratchSlot , CellDeltaScratchSlot , ForgetDeltaScratchSlot , InputDeltaScratchSlot , CandidateDeltaScratchSlot , OutputDeltaScratchSlot , CudnnOutputDeltaScratchSlot , CudnnInputDeltaScratchSlot } |
| enum | Gate { Forget , Input , Candidate , Output , GateCount } |
| using | GateViews = array<const TensorView*, GateCount> |
Public Member Functions | |
| void | set (Index, Index, Index, ActivationFunction new_activation_function=ActivationFunction::Tanh, ActivationFunction new_recurrent_activation_function=ActivationFunction::Sigmoid, Type new_compute_dtype=Type::FP32) |
| GateViews | gate_biases () const |
| GateViews | gate_weights () const |
| GateViews | gate_recurrent_weights () const |
| GateViews | gate_bias_gradients () const |
| GateViews | gate_weight_gradients () const |
| GateViews | gate_recurrent_weight_gradients () const |
| vector< TensorSpec > | parameter_specs () const override |
| vector< ParameterSlot > | parameter_slots () override |
| void | set_parameters_random () override |
| void | set_parameters_glorot () override |
| void | set_parameters_pytorch () override |
| void | forward_propagate (ForwardPropagation &, size_t, ForwardPropagationMode) override |
| void | back_propagate (ForwardPropagation &, BackPropagation &, size_t) const override |
 Public Member Functions inherited from opennn::Operator | |
| virtual | ~Operator ()=default |
| virtual vector< TensorSpec > | state_specs () const |
| virtual vector< SlotQuantization > | parameter_quantization () const |
| virtual void | link_parameters (span< const TensorView > views) |
| virtual void | link_gradients (span< const TensorView > views) |
| virtual void | link_states (span< const TensorView >) |
| virtual void | link_parameter_scales (span< const TensorView >) |
| bool | link_slots (span< const TensorView > views, TensorView *ParameterSlot::*member) |
| virtual void | initialize_states () |
| virtual void | set_weights_dtype (Type new_weights_dtype) |
| virtual void | to_JSON (JsonWriter &) const |
| virtual void | from_JSON (const Json *) |
| virtual void | load_state_from_JSON (const Json *) |
| TensorView & | get_input (ForwardPropagation &forward_propagation, size_t layer, size_t slot_index=0) const noexcept |
| vector< TensorView > & | get_inputs (ForwardPropagation &forward_propagation, size_t layer) const noexcept |
| TensorView & | get_output (ForwardPropagation &forward_propagation, size_t layer, size_t slot_index=0) const noexcept |
| TensorView & | get_output_delta (BackPropagation &back_propagation, size_t layer, size_t slot_index=0) const noexcept |
| TensorView & | get_input_delta (BackPropagation &back_propagation, size_t layer, size_t slot_index=0) const noexcept |
Additional Inherited Members | |
| Protected Member Functions inherited from opennn::CudnnRnnState | |
| unique_lock< mutex > | lock_backend_state () const |
| void | cudnn_rnn_forward_ (const CudnnRnnShapeSlot &, bool is_training, bool has_cell_state, const void *x, void *y, Buffer &forward_state, const function< CudnnRnnShapeSlot &()> &reconfigure) const |
| void | cudnn_rnn_backward_ (const CudnnRnnShapeSlot &, bool has_cell_state, const void *x, const void *y, const void *dy, void *dx, const Buffer &forward_state, Buffer &backward_scratch) const |
| CudnnRnnShapeSlot & | cudnn_setup_ (const CudnnRnnConfig &, Index input_features, Index output_features, Index time_steps, Index batch_size, bool for_training) const |
| CudnnRnnShapeSlot & | cudnn_setup_attempt_ (const CudnnRnnConfig &, Index input_features, Index output_features, Index time_steps, Index batch_size, bool for_training) const |
| void | cudnn_copy_weight_regions_ (int num_linear_layers, Index input_features, Index output_features, const TensorView *const *matrices, const TensorView *const *vectors, Buffer &packed_weights, bool to_cudnn) const |
| void | cudnn_pack_weights_ (int num_linear_layers, Index input_features, Index output_features, const TensorView *const *weights, const TensorView *const *biases, Buffer &forward_state, uint64_t parameters_version) const |
| void | cudnn_unpack_gradients_ (int num_linear_layers, Index input_features, Index output_features, const TensorView *const *weight_gradients, const TensorView *const *bias_gradients, Buffer &backward_scratch) const |
| void | prepare_cudnn_forward_state_ (Buffer &, bool is_training, const CudnnRnnShapeSlot &) const |
| string | cudnn_rnn_configuration_ (const CudnnRnnShapeSlot &, const char *mode) const |
| void | drive_cudnn_forward_ (const CudnnRnnDims &, const TensorView &input, TensorView &sequence_output, TensorView &output, TensorView &cudnn_input_sequence, TensorView &cudnn_output_sequence, Buffer &forward_state, bool is_training, uint64_t parameters_version) const |
| void | drive_cudnn_backward_ (const CudnnRnnDims &, const TensorView &input, const TensorView &sequence_output, const TensorView &output_delta, const TensorView &cudnn_input_sequence, const TensorView &cudnn_output_sequence, TensorView &input_delta, TensorView &sequence_delta_scratch, TensorView &input_delta_scratch, const Buffer &forward_state, Buffer &backward_scratch) const |
| Protected Attributes inherited from opennn::CudnnRnnState | |
| BackendState | backend_state |
Member Typedef Documentation
◆ GateViews
| using opennn::LSTMOperator::GateViews = array<const TensorView*, GateCount> |
Member Enumeration Documentation
◆ BackwardSlot
◆ ForwardSlot
◆ Gate
Member Function Documentation
◆ back_propagate()
|
overridevirtual |
Reimplemented from opennn::Operator.
◆ forward_propagate()
|
overridevirtual |
Reimplemented from opennn::Operator.
◆ gate_bias_gradients()
|
inline |
◆ gate_biases()
|
inline |
◆ gate_recurrent_weight_gradients()
|
inline |
◆ gate_recurrent_weights()
|
inline |
◆ gate_weight_gradients()
|
inline |
◆ gate_weights()
|
inline |
◆ parameter_slots()
|
overridevirtual |
Reimplemented from opennn::Operator.
◆ parameter_specs()
|
overridevirtual |
Reimplemented from opennn::Operator.
◆ set()
| void opennn::LSTMOperator::set | ( | Index | , |
| Index | , | ||
| Index | , | ||
| ActivationFunction | new_activation_function = ActivationFunction::Tanh, | ||
| ActivationFunction | new_recurrent_activation_function = ActivationFunction::Sigmoid, | ||
| Type | new_compute_dtype = Type::FP32 ) |
◆ set_parameters_glorot()
|
overridevirtual |
Reimplemented from opennn::Operator.
◆ set_parameters_pytorch()
|
overridevirtual |
Reimplemented from opennn::Operator.
◆ set_parameters_random()
|
overridevirtual |
Reimplemented from opennn::Operator.
Member Data Documentation
◆ activation_function
| ActivationFunction opennn::LSTMOperator::activation_function = ActivationFunction::Tanh |
◆ candidate_bias
| TensorView opennn::LSTMOperator::candidate_bias |
◆ candidate_bias_gradient
| TensorView opennn::LSTMOperator::candidate_bias_gradient |
◆ candidate_recurrent_weight_gradient
| TensorView opennn::LSTMOperator::candidate_recurrent_weight_gradient |
◆ candidate_recurrent_weights
| TensorView opennn::LSTMOperator::candidate_recurrent_weights |
◆ candidate_weight_gradient
| TensorView opennn::LSTMOperator::candidate_weight_gradient |
◆ candidate_weights
| TensorView opennn::LSTMOperator::candidate_weights |
◆ forget_bias
| TensorView opennn::LSTMOperator::forget_bias |
◆ forget_bias_gradient
| TensorView opennn::LSTMOperator::forget_bias_gradient |
◆ forget_recurrent_weight_gradient
| TensorView opennn::LSTMOperator::forget_recurrent_weight_gradient |
◆ forget_recurrent_weights
| TensorView opennn::LSTMOperator::forget_recurrent_weights |
◆ forget_weight_gradient
| TensorView opennn::LSTMOperator::forget_weight_gradient |
◆ forget_weights
| TensorView opennn::LSTMOperator::forget_weights |
◆ input_bias
| TensorView opennn::LSTMOperator::input_bias |
◆ input_bias_gradient
| TensorView opennn::LSTMOperator::input_bias_gradient |
◆ input_features
| Index opennn::LSTMOperator::input_features = 0 |
◆ input_recurrent_weight_gradient
| TensorView opennn::LSTMOperator::input_recurrent_weight_gradient |
◆ input_recurrent_weights
| TensorView opennn::LSTMOperator::input_recurrent_weights |
◆ input_weight_gradient
| TensorView opennn::LSTMOperator::input_weight_gradient |
◆ input_weights
| TensorView opennn::LSTMOperator::input_weights |
◆ output_bias
| TensorView opennn::LSTMOperator::output_bias |
◆ output_bias_gradient
| TensorView opennn::LSTMOperator::output_bias_gradient |
◆ output_features
| Index opennn::LSTMOperator::output_features = 0 |
◆ output_recurrent_weight_gradient
| TensorView opennn::LSTMOperator::output_recurrent_weight_gradient |
◆ output_recurrent_weights
| TensorView opennn::LSTMOperator::output_recurrent_weights |
◆ output_weight_gradient
| TensorView opennn::LSTMOperator::output_weight_gradient |
◆ output_weights
| TensorView opennn::LSTMOperator::output_weights |
◆ recurrent_activation_function
| ActivationFunction opennn::LSTMOperator::recurrent_activation_function = ActivationFunction::Sigmoid |
◆ return_sequences
| bool opennn::LSTMOperator::return_sequences = false |
◆ time_steps
| Index opennn::LSTMOperator::time_steps = 0 |
